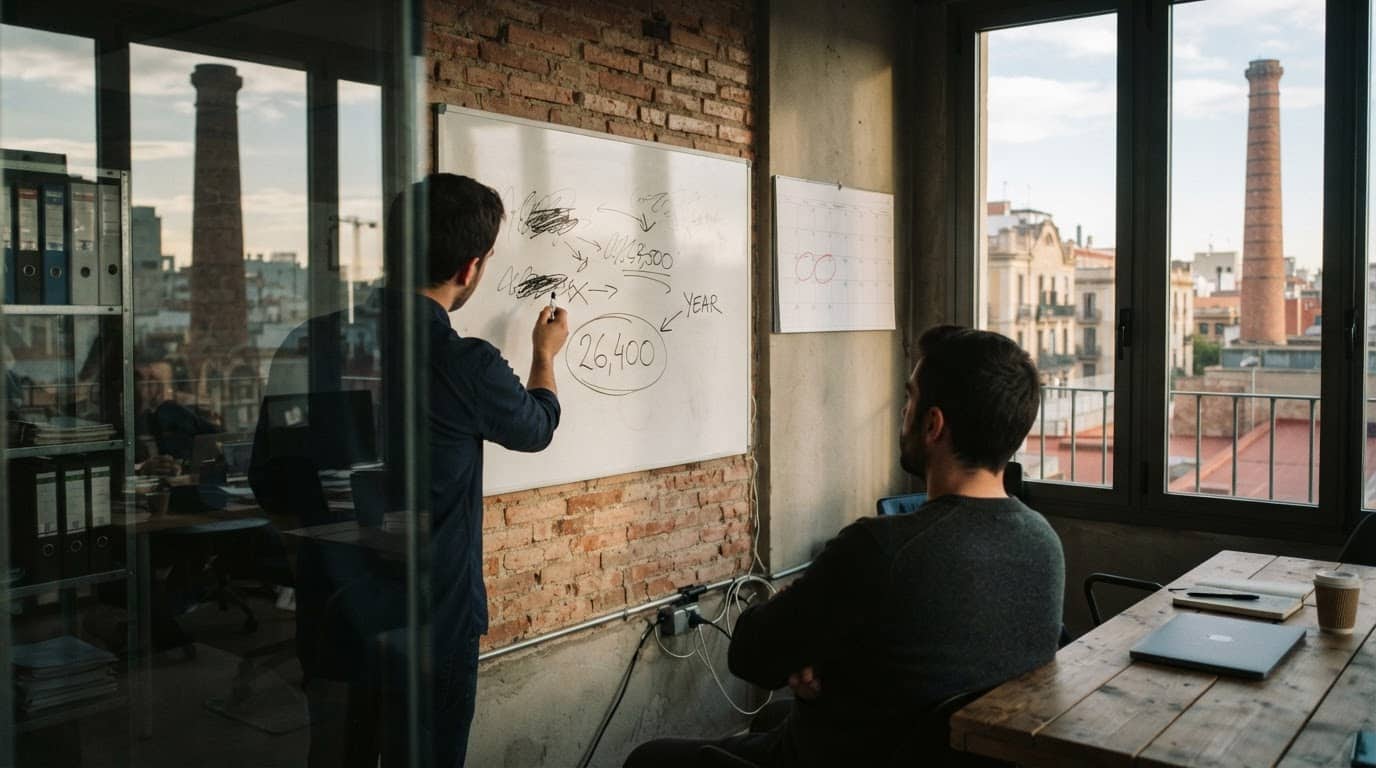
Here is an illustration, invented for this post: a support team pilots an AI assistant for two weeks. Eight agents report that it saves ten minutes on a ticket. Someone multiplies: ten minutes, twelve tickets a day, 220 working days, and the pilot’s eight agents become all sixty in the department. The business case now shows AI pilot savings of 26,400 hours a year, the equivalent of fifteen full-time people.
Nobody observed that number. What was observed is eight volunteers, two weeks, and a time saving they estimated themselves. The multiplication turned a small, favourable observation into a guarantee about what will happen in a year, and the deck presents it as fact.
The arithmetic is correct but the evidence is not. Every step changes what kind of claim is being made: from eight people said to the department will, from two weeks dedicated to piloting to every working day, no matter what’s going on, from handpicked volunteers to everyone. The pilot period is usually the best one available, with enthusiasts, easy tickets, and a novelty that will fade. Also, nothing in the formula includes the licence, the tokens, the time spent reviewing the output, or what happens to quality.
The vendor version
Vendors do the same thing at a larger scale. Ed Zitron, a committed critic of the AI industry, writes that “Reporting ‘run rates’ is a marketing exercise”. The mechanism is the one in my illustration: take the best recent period, multiply it, and present the result as guaranteed annual recurring revenue (ARR). When the Financial Times reported that OpenAI had told investors its annualised revenue was approaching $50 billion, about $20 billion below the figure that had been circulating, the gap came from how partner sales were counted. I have not read the FT piece itself: Dealroom’s summary is my source. The gap shows how fragile an annualised number is.
The vendor version at least gets picked apart in public. The internal one goes into a budget paper and nobody checks it. I see it often: the best of a few days of data, multiplied by 365, which assumes every future day looks like the best day that happened to be measured.
I have argued before that output counts are a poor stand-in for value, in AI Productivity Metrics, and that output outruns what an organisation can absorb, in The AI Acceleration Trap. This is a different failure. A team can pick the right outcome and still report a number that nobody should trust.
Where self-report drifts
The best evidence that estimated time saved can be wrong comes from METR. In a 2025 trial, 16 experienced open-source developers worked on 246 issues, randomly allowed or not allowed to use AI. They expected AI to make them 24% faster. Afterwards they still believed it had made them 20% faster. The clock said they were 19% slower.
That is one study of early-2025 tools with a small sample, and METR itself calls the results out of date. Its February 2026 follow-up estimated a 4% speed-up, with a confidence interval that includes zero, and METR says that data is unreliable because developers refused to work without AI. The conclusion is that even people who measure this for a living struggle to get a clean number, so a ten-minute claim from a pilot deserves more doubt, not less.
Gergely Orosz spoke to 27 companies about what their engineers spend on AI. The ROI question, he writes, is a question that few companies seem able to answer, at least for now. I used his pull-request figures in my acceleration post; here the point is narrower. Few of the companies he spoke to could say what the spend had returned.
Four questions before it gets used
Before a pilot number goes into a deck or a budget, I ask four things:
- Was it observed? Was the saving seen over real work, or is it someone’s estimate of time saved?
- Is the period comparable? Is the baseline the same mix of work and the same season, with typical staff as well as enthusiasts? Or is it the best fortnight against an average one?
- Are cost and quality counted? Does it include licences and tokens, review and rework time, and a quality measure like reopened tickets? A saving that moves the work to a reviewer is not a saving.
- Who would notice if it were false? A named person, a report, or a dated check. If nobody would notice, it is not a measure.
Then report two numbers side by side: what you observed, with dates, and what you assume if it holds. Put them in different type, and add a date when someone will check.
A forecast is allowed
Projecting is fine. A pilot is meant to be extrapolated, and a business case with no projection never gets funded. The problem is passing a forecast off as a result. A good one says what was observed, over what dates, and what was assumed to get from there to a year, and it can be wrong in a way someone will see. It costs one extra column and a calendar entry.
Find the one annualised savings figure currently sitting in a deck and ask who would notice if it were wrong. An annualised number is a forecast wearing a result’s clothes. Show me the week you watched.

Leave a Reply